AI knowledge base for company documents
Ask your documents a question. Get the answer and the page it came from.
Acasa Labs builds an AI knowledge base for company documents: your manuals, policies, contracts, and past projects become something your team can ask questions of, with every answer citing the document and page. NoteTube answers from each user's own uploaded material, and SigmaCPM drops any value it cannot find on the cited page.
The problem
The answer is in a PDF somewhere. Nobody knows which one.
Your company knows a lot, but it is spread across shared drives, email attachments, old proposals, and the heads of the people who have been there longest. New staff ask the same questions, and senior staff stop work to answer them. Searching the drive finds the file name, not the answer. A public chatbot answers confidently from the internet, which is worse than no answer when the question is about your own policy or contract.
What we build
- 01
Your documents, ready to be asked
PDFs, Word files, scans, and pages from your tools are read, split into passages, and indexed, and new files are added as they arrive.
- 02
Answers with a citation
Every answer shows the document and page it came from, so your team can check it in one click instead of trusting it.
- 03
Access that follows your rules
People only get answers from documents they are allowed to see, so HR files stay with HR.
- 04
Where your team already works
A search page, a chat inside your own app, or a connection to the AI tools your team already uses.
From production
Document AI we run in production.
Answers from the user's own material
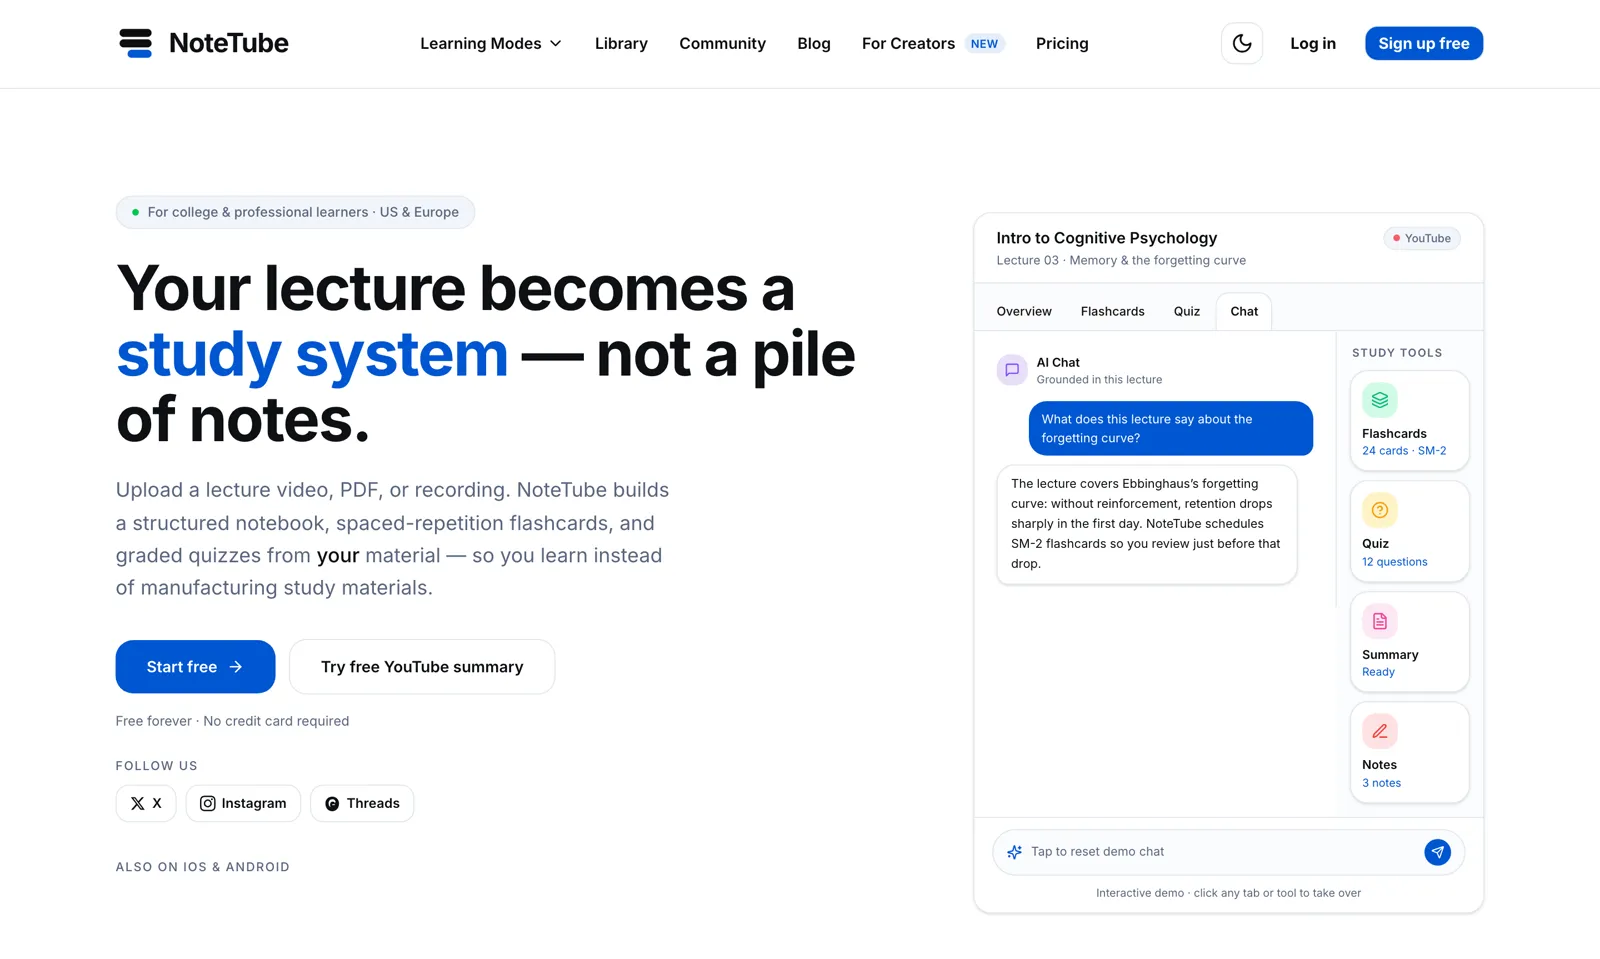
NoteTubeNoteTube parses videos, PDFs, DOCX, images, articles, and audio, and stores them in Qdrant scoped per user and per session. Chat answers come from that material, not the open web.
No quote on the page, no answer
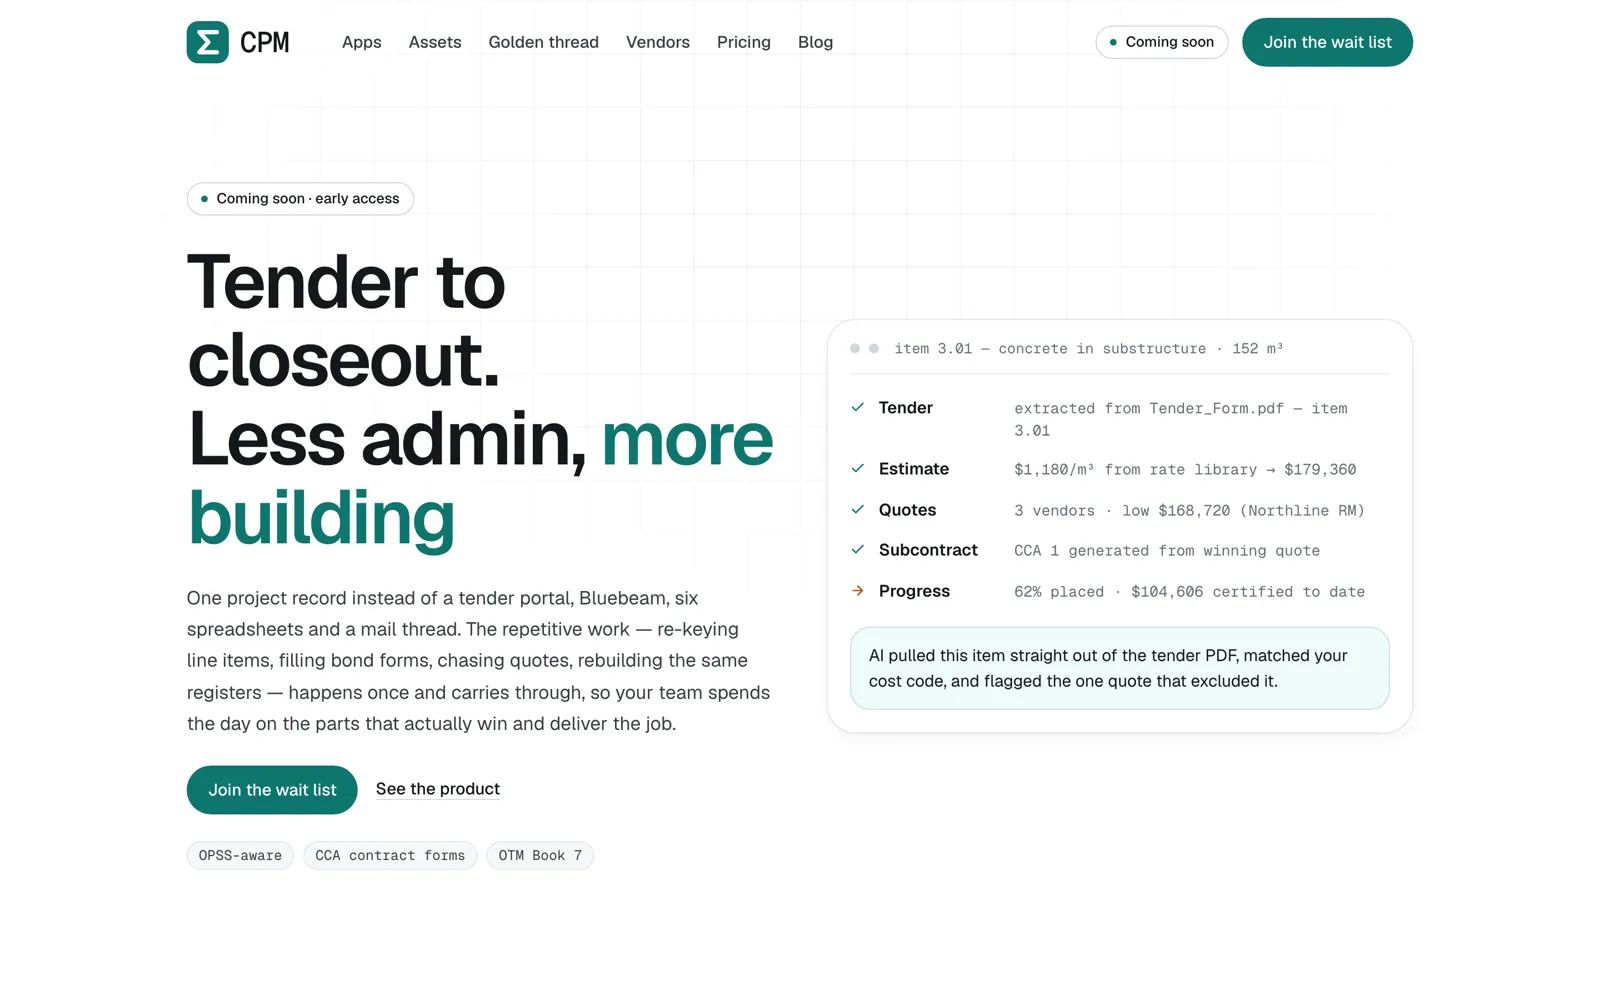
SigmaCPMSigmaCPM requires every extracted value to come with a quote, and checks that the quote is on the cited page. If it is not there, the value is dropped instead of guessed.
Ask from ChatGPT, Claude, or Cursor
NoteTubeNoteTube runs a remote MCP server on Cloudflare Workers with OAuth and audience-checked tokens, so outside AI tools can query a user's notes without being handed the whole library.
Keys kept away from the apps
NoteTubeNoteTube's AI keys live only in a separate FastAPI service. The web and mobile apps never see them, and model choice runs across five providers.
Honest trade-offs
When a better search box is enough
If your documents are few, well named, and in one place, the search in Google Drive or SharePoint, or the AI built into it, may answer most questions. A custom knowledge base pays off when documents are spread across systems, when answers must be checked against the source, when access rules matter, or when the knowledge base sits inside your own product. For the engineering behind it, see our RAG development page.
What we reach for
- FastAPI
- Qdrant
- Postgres with pgvector
- OCR
- OpenAI, Anthropic, Gemini
- MCP servers
Proof
Shipped, not pitched.
01Our product
NoteTube
A lecture becomes a study system: chat, flashcards, quizzes, all grounded in the source.
An AI learning platform that turns PDFs, YouTube lectures, recordings, and notes into a structured notebook with grounded chat, spaced-repetition flashcards, and graded quizzes.
Web · iOS · Android · Chrome extension · MCP server
02Our product
SigmaCPM
Construction project management where AI reads the tender and shows its work.
One project record for civil contractors, from tender to closeout: bids, contracts, RFIs, vendor quotes, and drawings. The AI pulls line items and bond terms out of tender PDFs and cites the page for every value.
Web · API · Chrome extension
Questions
AI knowledge base questions we get asked.
What documents can it read?
PDFs, Word files, slides, scanned pages through OCR, web pages, and text exported from your tools. NoteTube also handles video and audio by transcribing them first.
How do we know the answers are right?
Every answer cites the document and page, so a person can check it. We also test it on questions your team writes, with known answers, before anyone relies on it.
Will our documents be used to train someone's AI?
We use model providers' business APIs, whose terms say API data is not used for training by default, and we can run open models on your own servers when documents cannot leave.
Can it connect to Google Drive or SharePoint?
Yes, through their APIs, so new and changed files are picked up on a schedule and removed files drop out of the answers.
How is this different from your RAG development service?
Same engineering, different starting point. This page starts from the business problem of finding answers in company documents. The RAG page covers retrieval, reranking, and evaluation in depth.
AI knowledge base for company documents
Bring ten questions your team asks every week.
Thirty minutes on where your documents live and who needs answers. You leave with a written plan: scope, timeline, and a number.