OCR data extraction software, built for your documents
Stop typing what is already written on the page.
Acasa Labs builds OCR data extraction software that reads scanned and digital documents, such as tenders, invoices, purchase orders, and forms, and turns them into clean data in your system. Each value points to where it was found. SigmaCPM extracts tender line items this way, and Acasa Sentinel reads number plates from video.
The problem
Someone on your team retypes documents all day.
Invoices, purchase orders, delivery notes, application forms, and tenders arrive as PDFs and phone photos. A person reads each one and types it into the system, line by line. It is slow, it is boring, and the mistakes show up later as wrong payments and wrong quotes. Basic OCR turns the scan into text, but text is not data: it does not know which number is the total and which is the account number.
What we build
- 01
Reading scans and photos
OCR for scanned pages and phone photos, with retries for the pages that come out badly, so old and messy documents still work.
- 02
Pulling out the fields you need
Totals, dates, line items, names, and reference numbers extracted into a structured record that matches your system.
- 03
A person checks what is unsure
Values the system is not confident about go to a review screen with the source highlighted, instead of straight into your books.
- 04
Straight into your system
Clean data goes to your ERP, accounting software, or database through its API, with a log of every document processed.
From production
Extraction that shows its work.
Every value cited to a page
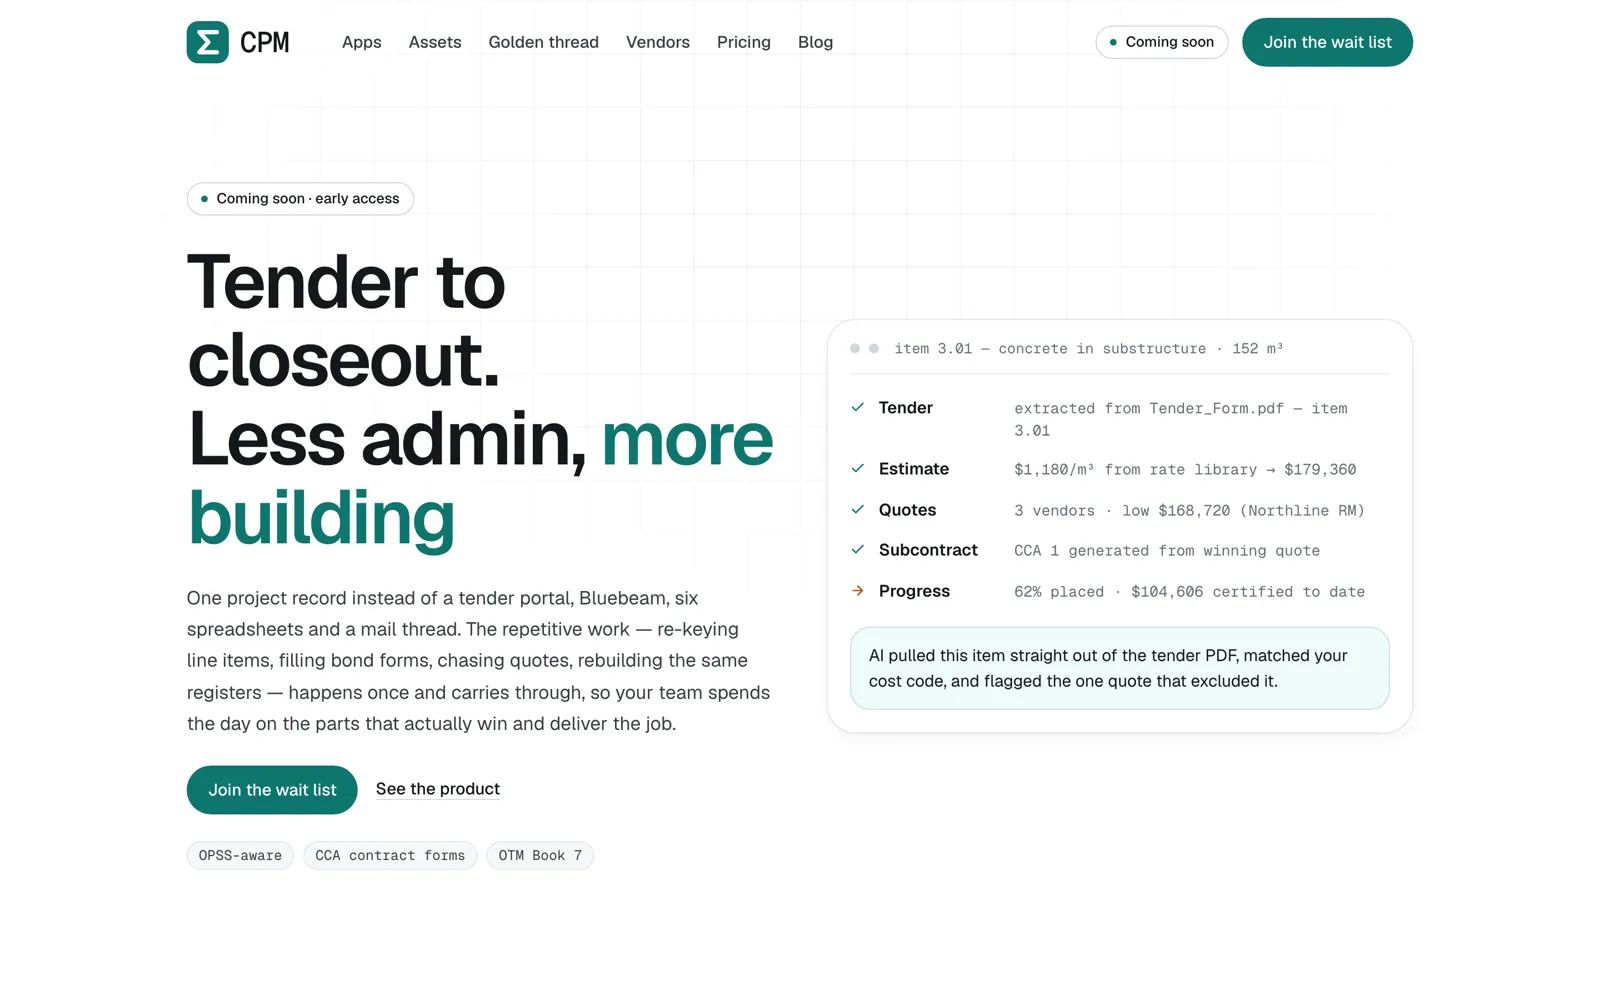
SigmaCPMIn SigmaCPM, every value the model pulls from a tender must come with a quote, and the quote must be found on the cited page. If it is not there, the value is dropped.
A second pass that disagrees
SigmaCPMBond terms are re-checked by a second, adversarial model run. When the two disagree, the value lands in a disputed state for a person to resolve.
OCR before extraction
SigmaCPMScanned tender pages go through OCR with retry handling, and the system picks out the likely pages first, so the model reads the right pages instead of the whole package.
OCR that expects mistakes
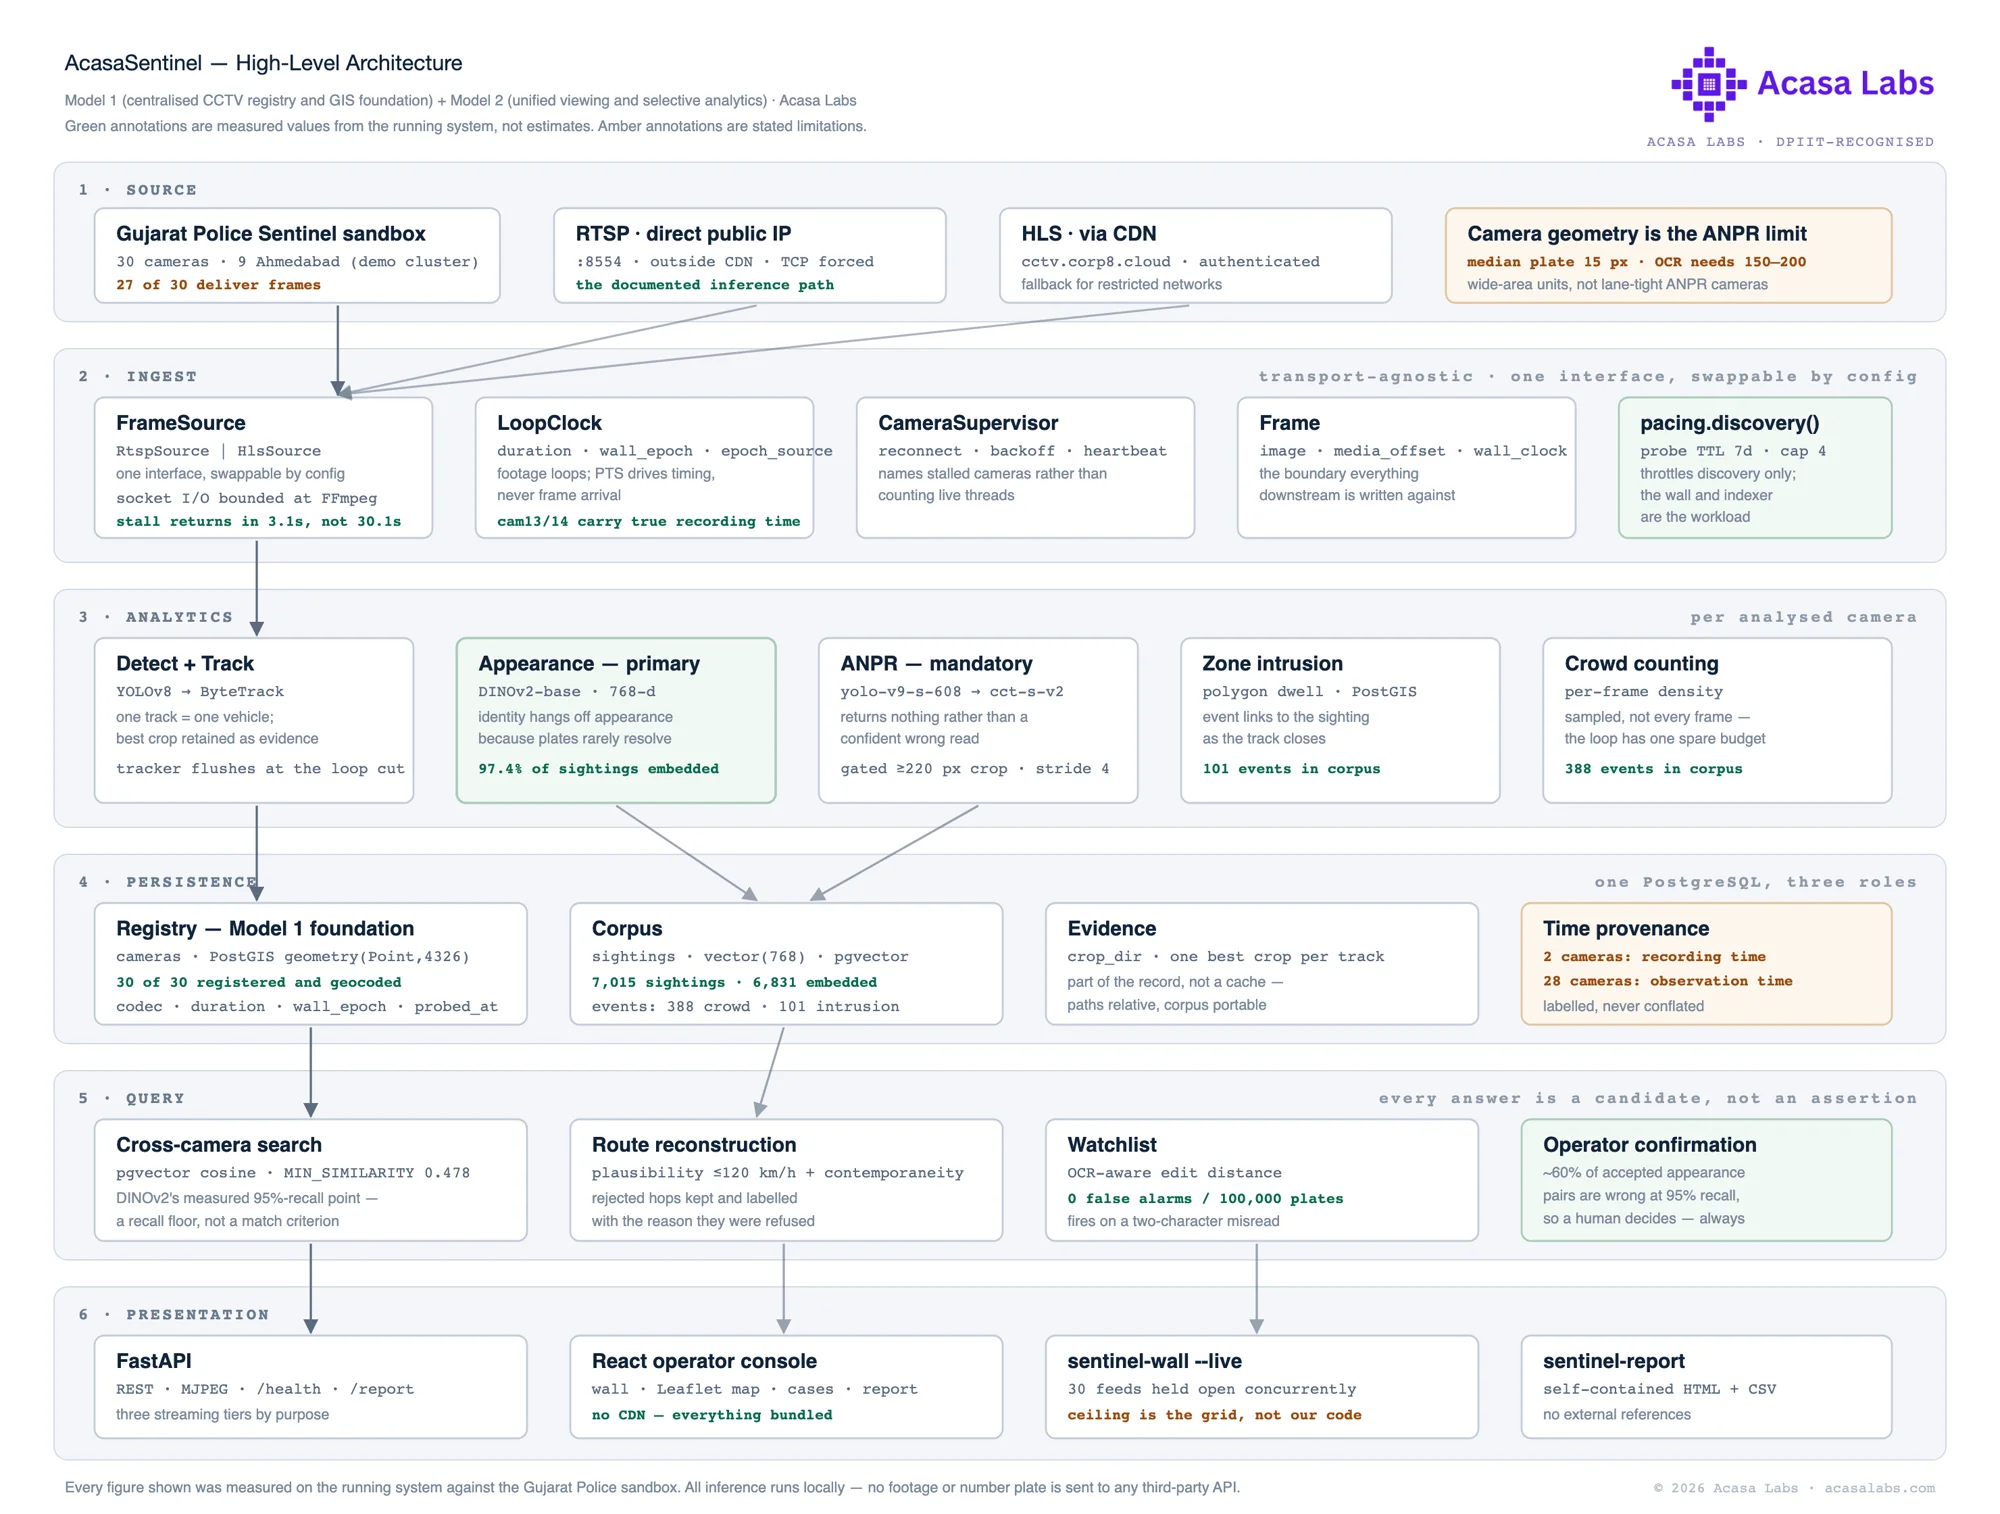
Acasa SentinelAcasa Sentinel reads number plates per vehicle with a multi-frame vote, and matches the watchlist with OCR-aware fuzzy matching, so a misread O for 0 still matches.
Honest trade-offs
When an off-the-shelf OCR tool is enough
If your documents are standard invoices or receipts in common layouts, an off-the-shelf tool, or the scanning built into your accounting software, will get most of the way for a monthly fee. Custom extraction pays off when the documents are specific to your trade, when you need line items rather than totals, when a wrong value is expensive, or when the result has to go into your own system without someone retyping it.
What we reach for
- OCR
- OpenRouter LLMs
- Django REST Framework
- FastAPI
- Postgres
- Java PDFBox
- ONNX models
Proof
Shipped, not pitched.
01Our product
SigmaCPM
Construction project management where AI reads the tender and shows its work.
One project record for civil contractors, from tender to closeout: bids, contracts, RFIs, vendor quotes, and drawings. The AI pulls line items and bond terms out of tender PDFs and cites the page for every value.
Web · API · Chrome extension
02Case study
Acasa Sentinel
Give it a number plate. It returns the vehicle's route across a CCTV network.
A vendor-neutral video analytics system built for the Gujarat Police Hackathon Innovation Challenge 2026. It reads number plates, re-identifies vehicles by appearance across cameras, reconstructs routes, and raises watchlist alerts for an operator to confirm.
Operator console (web) · API
Questions
OCR data extraction questions we get asked.
Which documents can it read?
Digital PDFs, scanned pages, and phone photos, in printed text. Handwriting is possible but less reliable, and we test your samples before promising anything.
How accurate is it?
That depends on your documents, so we measure it on a sample of yours before the build and report the result. The design assumes some values will be unsure and sends those to a person.
Can it handle documents in Hindi or Gujarati?
Modern OCR handles many Indian scripts. Accuracy varies by script and print quality, so we test on your real documents first.
Does the data go to an outside AI company?
It can stay in-house. Acasa Sentinel runs all its inference locally, and we can do the same for documents that cannot leave your servers.
Can it go straight into Tally, Zoho, or our ERP?
If the software has an API or an import format, yes. We map the extracted fields to it and keep a log of every document posted.
OCR data extraction software, built for your documents
Send us ten real documents.
Thirty minutes on what arrives, who types it, and where it goes. You leave with a written plan: scope, timeline, and a number.